Build a MotherDuck Warehouse with dbt and Deploy a Dive
I want to build a MotherDuck warehouse from scratch with dbt-duckdb and then ship a Dive on top of the mart tables. Help me adapt the "Build a MotherDuck Warehouse with dbt and Deploy a Dive" recipe to my own data and use case, using it as a guide: https://motherduck.com/docs/cookbook/dbt-duckdb-dwh-starter
A minimal dbt-duckdb starter for building a MotherDuck warehouse end to end and
shipping a Dive on top of it. It reads the Common Crawl domain hyperlink graph
(which sites link to a target domain) straight from remote gzip files, joins it
with the Hacker News dataset, and builds tested mart tables. A deploy script then
publishes a Dive that visualizes the marts. It shows the MotherDuck pattern of
turning large remote CSV/gzip sources into performant tables with dbt, combining
datasets across a share, and deploying a Dive as code.
With this setup you'll learn how to:
- Turn large CSV/gzip source data into performant MotherDuck tables
- Combine data from different sources (Common Crawl + a Hacker News share) with dbt
- Deploy a MotherDuck Dive from validated, tested marts
How it works
The dbt project layers staging, intermediate, and mart models, each in its own
schema suffix (<DBT_SCHEMA>_stg, _int, _mart):
models/staging/commoncrawl: source-backed tables over the Common Crawl remote gzip files for the configuredcommoncrawl_snapshot. The default snapshotcc-main-2026-jan-feb-marexposes three outputs:domain-ranks(PageRank and harmonic centrality),domain-vertices(domain ids and reversed host names), anddomain-edges(domain-to-domain links, filtered to your configured domains).models/staging/hackernews: Hacker News stories. The model attaches the public Hacker News MotherDuck share before reading it:
ATTACH IF NOT EXISTS 'md:_share/hacker_news/de11a0e3-9d68-48d2-ac44-40e07a1d496b' AS hacker_news;
models/intermediate: target-domain joins and edge expansion.models/marts: tested tables ready to query, and the source the Dive reads.
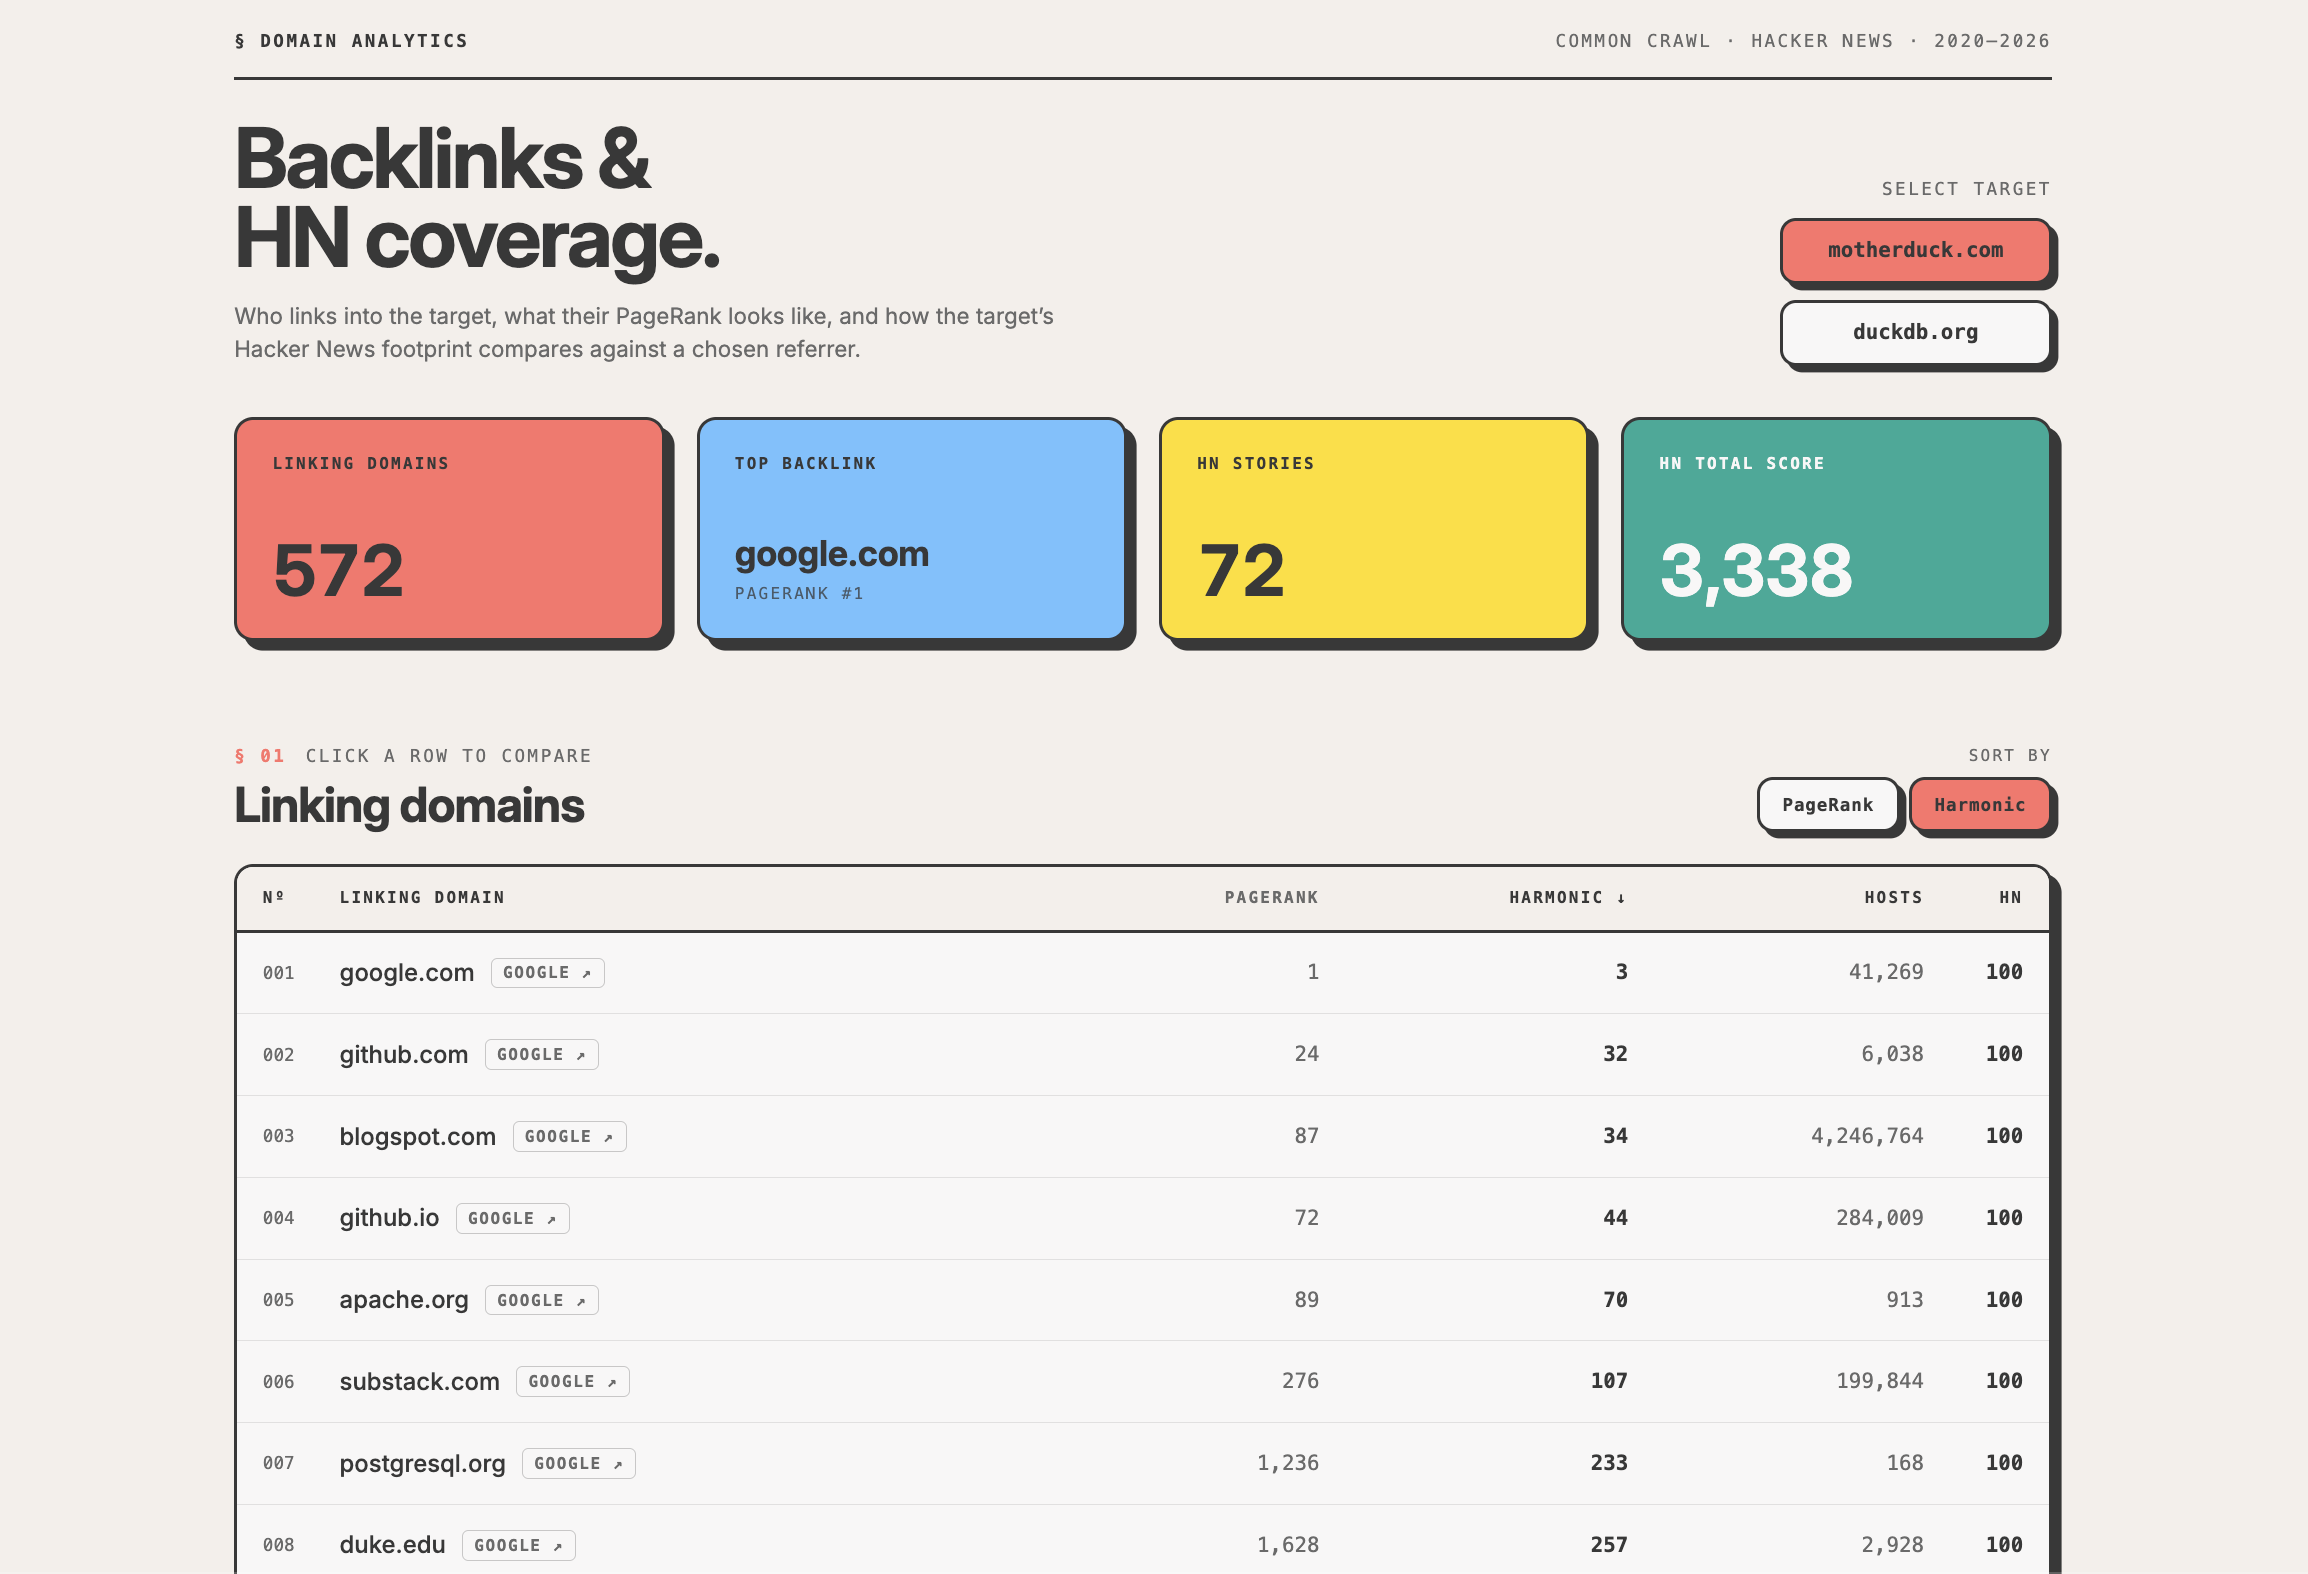
The Dive lives in dives/backlinks-hn/dive.tsx and queries the mart tables. The
deploy script (scripts/deploy-dive.sh) reads dives/<name>/dive-manifest.json,
loads the dive.tsx source with DuckDB read_text(), substitutes the database
and _mart schema into the source, and creates or updates the Dive in MotherDuck
with the MD_CREATE_DIVE / MD_UPDATE_DIVE_CONTENT functions.
Questions to answer
- Which target domain(s) should the link graph and HN coverage focus on (
commoncrawl_domains)? - Which MotherDuck database and base schema, and dev or prod (
DBT_DUCKDB_PATH,DBT_SCHEMA,--target)? - Which Common Crawl snapshot, and how many HN stories per domain (
commoncrawl_snapshot,hackernews_max_stories_per_domain)? - Is the large Common Crawl edges download acceptable (see Caveats), or should the scope be narrowed first?
- Deploy the Dive, and as a preview or to production?
- Is a MotherDuck account and token available, with access to the Hacker News share?
Caveats
- The Common Crawl edges file is large (~14GB).
stg_commoncrawl__domain_edgesis materialized incrementally so it is not re-downloaded on every run; avoid a casual--full-refreshof that model. DBT_DUCKDB_PATHandDBT_SCHEMAmust match between the dbt build and the Dive deploy. If they differ, the Dive points at a database/_martschema that the build did not populate and renders empty.- The Hacker News staging model attaches a MotherDuck share (
md:_share/hacker_news/...); the run needs access to that share. scripts/deploy-dive.shrequires theduckdbCLI andjqon PATH andMOTHERDUCK_TOKENset; it exits early if any are missing.- The deploy expects a unique Dive title: if more than one Dive already shares the title it errors instead of guessing which to update. Use
PREVIEW_BRANCHfor non-production deploys. threads: 24inprofiles.ymlis aggressive; lower it for smaller machines or plans.
What you'll adjust
| Setting | Purpose | Options / example |
|---|---|---|
commoncrawl_domains (dbt_project.yml vars) | The target domains the link graph and HN stories are filtered to. | [motherduck.com, duckdb.org]; add your own domains |
commoncrawl_snapshot (dbt_project.yml vars) | Which Common Crawl web-graph snapshot to read. | cc-main-2026-jan-feb-mar |
hackernews_max_stories_per_domain (dbt_project.yml vars) | Cap on HN stories pulled per domain. | 100 |
DBT_DUCKDB_PATH (env) | MotherDuck database dbt builds into. Must match the Dive deploy. | md:my_db (dev), md:dbt_prod (prod) |
DBT_SCHEMA (env) | Base schema; models land in <DBT_SCHEMA>_stg/_int/_mart. Must match the Dive deploy. | dbt_dev (dev), dbt_main (prod) |
dbt --target (profiles.yml) | Which profile output to use. | dev (default), prod |
threads (profiles.yml) | dbt thread count. | 24; lower it for smaller machines or plans |
MOTHERDUCK_TOKEN (env) | MotherDuck access token for dbt and the Dive deploy. | a token from the MotherDuck UI |
dives/backlinks-hn/dive.tsx + dive-manifest.json | The Dive's React/SQL source and its title/description. | edit tiles, queries, title |
PREVIEW_BRANCH (env, deploy) | Appends a branch name to the Dive title so a preview does not overwrite production. | $(git branch --show-current) |
Run it
Prerequisites: a MotherDuck account and access token, and uv. The Dive deploy
also needs the duckdb CLI and jq on your PATH.
uv sync
export MOTHERDUCK_TOKEN="..."

# Validate, then build the warehouse (dev target by default)
uv run dbt debug --profiles-dir .
uv run dbt parse --profiles-dir .
uv run dbt build --profiles-dir .
Domains are configured in dbt_project.yml under commoncrawl_domains; add more
domains there as needed. Create the target MotherDuck database first if it does
not already exist.
Deploy the dive
Build the dbt project first, then deploy the Dive. DBT_DUCKDB_PATH and
DBT_SCHEMA must match the values used for the build, because the deploy script
substitutes the database and ${DBT_SCHEMA}_mart schema into the Dive source:
export MOTHERDUCK_TOKEN="..."
export DBT_DUCKDB_PATH="md:my_db"
export DBT_SCHEMA="dbt_dev"
uv run dbt build --profiles-dir .
./scripts/deploy-dive.sh backlinks-hn
For production, use your prod database and schema for both the build and deploy:
export DBT_DUCKDB_PATH="md:dbt_prod"
export DBT_SCHEMA="dbt_main"
uv run dbt build --target prod --profiles-dir .
./scripts/deploy-dive.sh backlinks-hn
For a preview that does not overwrite the production Dive, set PREVIEW_BRANCH;
the script appends the branch name to the Dive title:
PREVIEW_BRANCH="$(git branch --show-current)" ./scripts/deploy-dive.sh backlinks-hn
The script prints the deployed Dive URL.
Files
dbt_project.yml- project config and thevarsknobs (commoncrawl_domains,commoncrawl_snapshot,hackernews_max_stories_per_domain) plus per-layer schema and materialization.profiles.yml-devandprodDuckDB outputs readingDBT_DUCKDB_PATH/DBT_SCHEMAfrom the environment; the token comes fromMOTHERDUCK_TOKEN.models/staging/- source-backed tables:commoncrawl/(the three Common Crawl outputs over remote gzip, edges materialized incrementally) andhackernews/(reads the attached Hacker News share).models/intermediate/- target-domain joins and edge expansion.models/marts/- tested mart tables the Dive queries (mart_domain_backlinks,mart_domain_link_graph,mart_hackernews_domain_stories).macros/commoncrawl.sql- helpers for building the Common Crawl source URLs and reads.dives/backlinks-hn/- the Dive:dive.tsx(React + SQL source with__DBT_DATABASE__/__DBT_MART_SCHEMA__placeholders) anddive-manifest.json(title, description, source file).scripts/deploy-dive.sh- deploys a Dive fromdives/<name>/using the DuckDB CLI and theMD_CREATE_DIVE/MD_UPDATE_DIVE_CONTENTfunctions.pyproject.toml/uv.lock- Python dependencies (dbt-duckdb) managed withuv.assets/backlinks-hn-dive.png- screenshot of the deployed Dive.
Learn more
- Common Crawl Web Graph Index: https://data.commoncrawl.org/projects/hyperlinkgraph/cc-main-2026-jan-feb-mar/index.html
- Hacker News dataset: https://motherduck.com/docs/getting-started/sample-data-queries/hacker-news/
- dbt-duckdb: https://github.com/duckdb/dbt-duckdb
- For Dive authoring, required databases, and deployment, run the
get_dive_guideMCP tool. For deeper MotherDuck or DuckDB questions, useask_docs_question.